Links for November 2026
1: Abbe, Boix-Adserà, and Misiakiewicz on the merged-staircase property.
I previously conjectured that neural networks can sidestep the bias-variance tradeoff because real-world target functions, though highly nonlinear and high-dimensional, have low-dimensional structure.
But there is an even stronger conjecture one can make. It’s not just that the nonlinear structure is confined to a low-dimensional subspace. We can go even further and posit that the complex nonlinear structure is in some sense composed of simpler low-dimensional structure. This compositional structure would allow you to learn the simple parts of the task first and then use what you’ve learned to help learn the more complicated parts.
In this paper, Abbe et al. introduce a class of functions called staircase functions, which have this structure. Consider the following two functions:
\[h_1(z) = z_1 z_2 z_3, \qquad h_2(z) = z_1 + z_1 z_2 + z_1 z_2 z_3\]Naively, one could say that both of these functions are equally complex, as they both involve three variables with the highest-order term being degree 3. However, there is a big difference in how easily gradient-based algorithms can learn the respective functions. For the first function, the network has to learn the complex structure “all at once”. In contrast, the second function is built such that gradient descent can systematically learn the simpler parts and then the more complicated parts of the function. The function $h_2$ is an example of a staircase function.
Specifically, for the second function, gradient descent can first learn $z_1$. Once it learns $z_1$, it’s much easier for it to learn $z_1 z_2$. It then becomes much easier again for it to learn $z_1 z_2 z_3$. You can climb the rungs of complexity step by step—like a staircase.
2: Jamie Simon on the scientific method and deep learning.
Jamie Simon is a deep learning researcher at UC Berkeley, where he runs the Feature Lab. He comes from a physics background, so he approaches deep learning with a heavy emphasis on the interplay between theory and experiment. Meditating on the nature of the scientific method, he boiled it down to a two-step process:
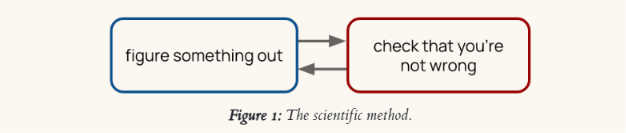
Figure from Simon 2025
So there are two steps: (1) figure something out, and (2) check that you’re not wrong. This is not a novel take on the scientific method, but I like it precisely because it’s so minimal.
For example, this minimal framework implies that science (in its idealized form) is agnostic to how you come up with a theory, as long as you subject it to sufficiently rigorous experimental examination.
This matters because deep learning is a field where experiments are unusually cheap—which means that more effort and creativity should be put into the “figuring something out” step.
3: Arthur Jaffe and Frank Quinn on “theoretical mathematics”.
In this paper, Jaffe and Quinn offer their taxonomy of “theoretical mathematics” versus “rigorous mathematics”. Their nomenclature of “theoretical mathematics” uses the word theoretical in the way that one uses it when describing theoretical physicists.
The idea is that a theoretical physicist doesn’t demonstrate facts about nature. Instead, one can view the job of theoretical physicists as coming up with elaborate, interesting, and clarifying “conjectures” about nature—which then have to actually be tested and verified by experimentalists. A “theoretical mathematician” is then one who makes interesting conjectures about the mathematical universe. In their analogy, rigorous proof plays the role in mathematics that experiment plays in physics.
They meditate on the strengths and dangers of speculative, “theoretical mathematics”. On the one hand, speculative mathematics can be hugely beneficial for the development of mathematics. While Hilbert provided tremendous value to mathematics by rigorously proving theorems, he also provided tremendous value by posing his famous Hilbert problems.
On the other hand, one can run into issues with this approach. They give multiple examples of “dead” fields arising in mathematics when someone provided what was essentially reasoned speculation without the required proof (and without being up front about this). When this happens, it can stall progress, because other mathematicians are dissuaded from working in the area (as they worry they would be viewed as just tidying up the details of someone else’s result).
4: Gwern on how one could create human-like neural networks.
While it’s striking how intelligent AI systems have become, it’s interesting to compare and contrast them with humans. LLMs still struggle mightily with tasks that humans find easy—and vice versa.
One way to characterize the difference is where AI and humans sit on the memorization-versus-generalization spectrum. LLMs know way more information than any individual human, being conversant in the obscure trivia of every scientific field. However, LLMs still struggle with certain types of creativity and generally perform less well in “fuzzy” domains than in verifiable ones. Humans, on the other hand, have relatively paltry memories, forgetting the majority of the information they encounter (how much of high school biology do you reckon you remember?). But humans are much better at finding robust, generally applicable abstractions from only small amounts of data.
Gwern conjectures that the difference might be that humans correspond to a learning system that is highly overparameterized, with a large step size and strong regularization—and that we could get more human-like neural networks by training them the same way. If you imagine the double-descent curve, humans would be well past the hump and deep into the strong-generalization regime. There is more discussion on LessWrong.
5: Elon Litman on generalization in deep learning.
This blog post covers similar themes to Gwern’s post. It starts with a meditation on an old short story by Jorge Luis Borges, “Funes the Memorious,” which concerns the themes of thinking and forgetting. Litman provides this delightful quote from the story:
I suspect [that Funes] was not very good at thinking. To think is to ignore (or forget) differences, to generalize, to abstract. In the teeming world of Ireneo Funes there was nothing but particulars.
The idea is that it’s not just that generalization is superior to memorization, but that they intrinsically trade off with each other. Being too intimate with the specific details can leave you unable to grok the full picture. You must choose between knowledge and understanding.
The blog post is a companion to an ambitiously titled paper, “A Theory of Generalization in Deep Learning” (with co-author Gabe Guo). I’ll admit, though, that even though I’ve skimmed through the paper, I don’t quite understand it. I’ll report back if I do.
6: Adam Brown on the Dwarkesh Podcast talking about general relativity.
On the Dwarkesh Podcast, physicist Adam Brown walks through general relativity, Einstein’s theory of gravity. Brown does a great job of putting physical motivation before formalism, and the chalkboard is a nice touch (though I admittedly just listened to the podcast version).
What’s remarkable about general relativity is that it was found with very little in the way of experimental data. Einstein had the discrepancy in the perihelion of Mercury (relative to the prediction from Newtonian gravity)…and that’s about it.
What drove the theory was high-level principles—like how to make special relativity consistent with accelerating reference frames—more so than experimental evidence. Indeed, it took quite a while for the experimental evidence to really roll in in a definitive way. While Eddington’s famous expedition to photograph the 1919 solar eclipse (general relativity gives a specific prediction for how much gravity should bend light, which can be tested during an eclipse) lent credence to the theory, other predictions of general relativity (e.g., gravitational redshift) took decades to be experimentally confirmed.
7: Oxford mathematicians Ben Green and James Maynard on AI in mathematics.
This is a discussion between mathematicians Ben Green and James Maynard, hosted by Jan Obłój, on the topic that everyone seems to be talking about these days: the chaos of AI-generated proofs in mathematics. It’s interesting to hear them describe their thought processes, as (in my opinion) they were a bit late to update to the situation.
If you’ve been following the progress in AI math for the last couple of years, then most of this year has been right on the trend line. A couple of years ago, AI models struggled with high school math problems. Then, in short order, they got gold at the 2025 IMO. By the end of 2025, they were already picking off some of the smaller Erdős problems. Green and Maynard remarked being very surprised by news like the disproof of the unit-distance conjecture and the counterexample to the Jacobian conjecture, whereas I think those results were basically in line with the trend.
Part of my lack of surprise might have been due to the fact that I’m not a mathematician: while I know that hard math problems are hard, I don’t really feel the AI math results on an emotional level, because AI has long since passed me in mathematical competence (which was probably around late 2024 when AI was roughly at the level of a not completely imcompetent grad student). Maybe I will start “feeling the AGI” once AI starts outputting entertaining blog posts.
What has caught me off guard has been all of the progress since Navier–Stokes got cracked in September. Navier–Stokes is one of the Millennium Prize Problems, math problems so hard that the Clay Mathematics Institute put up a million dollars for whoever solves each one.
Since then, there have been so many results that I’ve completely lost track of them all. There is a nice discussion of which results they found most mind-blowing, and a quick description of the quasi-Riemann hypothesis and why it’s significant. (The Riemann hypothesis is another of the seven Millennium Prize Problems.)
8: Michael Nielsen on writing.
Michael Nielsen is one of the few people who deserves the title of polymath. He started his career as a theoretical physicist, making many contributions to the field of quantum information (including co-authoring the textbook Quantum Computation and Quantum Information with Isaac Chuang). He has since moved on to projects such as metascience and machine learning.
While he wears many hats, here he is considering the question: is he a writer? To me, as someone whose familiarity with Nielsen is mainly through his blog posts and articles, the answer is obviously yes (and a good writer at that).
Though I get why he’s pondering the question in general. The canonical medium through which academics and intellectuals transmit ideas is written text, so there is a trivial sense in which every scientist is a writer. But it seems clear to me that Phil Anderson is more of a writer than Einstein, even though both of them were prolific producers of written text. How do we clarify that difference?
In practice, I would say that a scientist is a writer if their written output has value “for its own sake” (as in, independent of the information it contains). This is admittedly vague and perhaps not even a meaningful distinction, so one could operationalize it as: is there value in reading their work if you already understand the ideas it contains? If people continually revisit the actual text of your work, rather than reading second-hand material, then you function as a writer.
One example I would offer of a scientist who is also a writer is Paul Dirac. I’m currently reading through Dirac’s textbook The Principles of Quantum Mechanics, and I’m completely stunned by how fluid the prose is. (This is especially notable because Dirac is infamous for being one of the quietest people of all time.) I have already taken a couple of quantum mechanics classes, so the material (at least in the first half of the book) isn’t new to me, but the way that Dirac builds up the foundations, methodically, brick by brick, is completely mesmerizing. I would say that Paul Dirac is a writer.
9: The Mathematical AI Safety Institute.
I’ve previously talked about the website AI Safety for Mathematicians, which gives an overview of research directions for mathematicians interested in AI safety. Shortly after I posted that, they announced that they are launching a full-fledged venture called the Mathematical AI Safety Institute (MAISI): an institute where academics can go on sabbatical and work on AI safety. On the website, it says that they are looking for 10–30 faculty for January 2027 and 30–100 for September 2027.
Jacob Tsimerman, the Fields Medalist behind AI Safety for Mathematicians, is acting as the scientific director. On the scientific advisory panel are Ravi Vakil, Tim Gowers, Geoffrey Irving, and Paul Christiano.
I’m excited about this! This is as good a lineup as I could have asked for. Especially cool is how it blends the previously distinct academic and AI safety worlds. I associate Vakil and Gowers with traditional math academia, and Irving and Christiano with AI safety research efforts (though the latter two do have PhDs from Stanford and Berkeley, respectively, and significant academic research experience in their own right). Here’s the link to apply.
10: Sam Enright on the Daylight Computer.
The Daylight Computer is an Android tablet with a paper-like, black-and-white screen—something like a Kindle alternative, with a couple of advantages over the Kindle, such as a smoother interface.
What interests me about this review is not so much the product itself (though the details on how difficult the device was to procure were humorous) as the intended use case: escaping ubiquitous modern digital distractions.
Everyone knows at this point that our devices have fried all of our brains, but we are still in the midst of discovering the right countermeasures. One thing I do is keep my phone in black-and-white by default, as the iPhone’s default color palette is crazy vibrant and definitely addiction-optimized. Enright uses the Daylight Computer as a way to read books and articles away from his laptop—where he might be interrupted by the incessant pings of notifications and tempted away by all sorts of distractions.